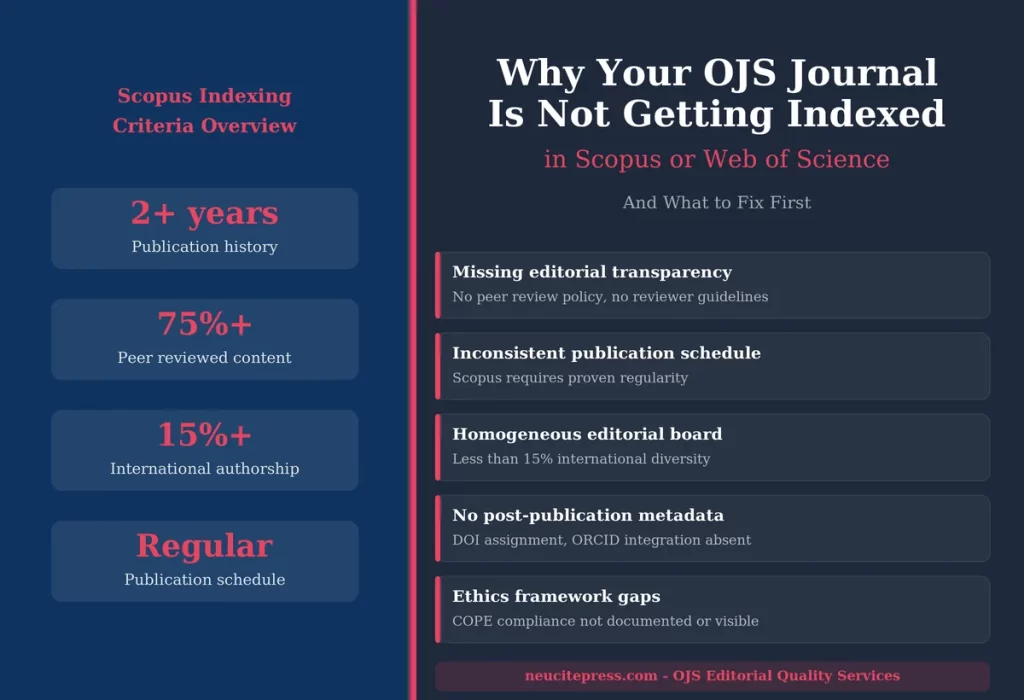
Google Scholar Indexing for Journals: Setup and Optimization
For any academic publication, achieving high visibility is the ultimate goal. In today’s digital landscape, one platform stands above the rest as the primary gateway for global research discovery. With over 389 million records, this service has become the most comprehensive scholarly index worldwide.
Reviewed by the NeucitePress Editorial Board — PhD academics, peer-reviewed editors and subject-matter specialists.
We understand the technical complexity and uncertainty that journal organizers often face. Many high-quality publications remain undiscovered simply because their technical setup does not meet specific requirements. This confusion is a significant pain point we address directly.
Our expertise is built on successfully guiding numerous publications through the intricate process. We have developed proven frameworks that demystify the entire procedure. This guide provides actionable steps to improve your discoverability and citation rates significantly.
Following our data-driven strategies can accelerate the timeline for success. Despite the platform’s proprietary algorithms, adherence to best practices dramatically improves outcomes. We provide the essential knowledge for sustained prominence in search results.
Key Takeaways
- Visibility on the premier academic search platform is critical for a journal’s reach and impact.
- The platform indexes an immense repository of over 389 million documents.
- Technical setup complexities are a common barrier to successful discovery.
- Expert guidance simplifies the compliance and optimization process.
- Implementing proven best practices can reduce the indexing timeline.
- Proper metadata is fundamental for search result prominence.
- Sustained visibility requires an ongoing, strategic approach.
Introduction: Unlocking Global Visibility with Scholarly Research
Over 100 million researchers worldwide rely on a single platform for their daily literature searches. This concentration of scholarly behavior creates an unprecedented opportunity for visibility that publishers cannot afford to miss.
Engaging Opening Hook with Compelling Statistics
The Renew Publishing Consultants report confirms academic indexes rank as “the most important discovery resource when searching for articles.” This platform consistently emerges as researchers’ preferred choice. Its comprehensive database contains over 389 million records, making it the world’s largest academic search engine.
For open access publications, integration with this system isn’t optional. It’s essential for making research discoverable, accessible, and citable. The platform’s ecosystem connects university libraries, research databases, and citation tools. Indexed papers receive exponentially more attention than their non-indexed counterparts.
Addressing Common Organizer Pain Points
Many publishers experience frustration with delayed processing times. While competitors’ content appears in search results within weeks, some wait 6-9 months. This creates significant competitive disadvantages.
Technical confusion about metadata requirements compounds these challenges. Uncertainty about why some articles succeed while others fail adds to the stress. The proprietary algorithms lack transparency, leaving organizers guessing.
We understand these pain points deeply. Our evidence-based approach demystifies the process. We’ve developed proven strategies that dramatically improve success rates. Proper optimization creates a virtuous cycle of increasing research impact through early visibility and citations.
Understanding Google Scholar Journal Indexing
Academic search platforms have revolutionized how research reaches global audiences through automated discovery systems. Unlike traditional databases requiring manual submissions, these platforms use sophisticated web crawlers that continuously scan for scholarly content.
How Google Scholar Works for Academic Publications
The platform operates through a three-phase system. First, it recognizes trusted sources like established publications and university repositories. Automated bots then crawl academic websites 24/7 to identify new content.
A critical principle many publishers misunderstand is “invitation by association.” Articles cited by already-indexed papers receive priority indexing. This creates a snowball effect for well-connected research.
Benefits of Being Indexed for Journals
Indexed articles experience remarkable visibility improvements. They reach over 100 million users worldwide through integrated library systems and reference tools.
The “Cited By” feature accelerates citation growth by up to 300%. This creates automatic bidirectional links between research and citing papers. Older, frequently-cited articles maintain prominence in search results.
For open access publishers, indexing ensures barrier-free research actually reaches maximum audiences. Authors benefit from automatic profile creation and citation tracking that builds academic reputation.
Technical Requirements and Metadata Guidelines
Technical precision forms the foundation of successful academic discovery. Proper metadata implementation enables automated systems to correctly identify and categorize your research. Without structured bibliographic information, even high-quality content remains invisible to discovery platforms.
We guide publishers through the essential technical specifications. Articles must exist as separate web pages with unique URLs. Files cannot exceed 5MB in size. The platform accepts HTML or searchable PDF formats, rejecting scanned images without text layers.
Implementing Correct HTML Meta Tags and PDF Standards
Machine-readable meta tags serve as the universal language for automated indexing. The system supports multiple schema types including Highwire Press and PRISM tags. Three core fields are mandatory for any article: citation_title, citation_author, and citation_publication_date.
Each author name requires a separate tag with consistent formatting. Avoid including affiliations or degrees. The title field must contain the paper title, not the publication name. Date formatting follows strict “YYYY/MM/DD” patterns.
PDF files demand searchable text layers with standard visual layout conventions. Titles should appear in the largest font, followed by author names in slightly smaller text. Reference sections need clear headings for proper parsing.
Crawling, Robots.txt, and File Format Essentials
Your website must allow complete access to crawling agents. The robots.txt file cannot block essential user agents. Proper configuration ensures efficient resource allocation while protecting dynamic spaces.
When separate PDF versions exist, the HTML page must include citation_pdf_url with the absolute file path. This prevents duplicate processing and ensures metadata association. Follow the official inclusion guidelines for comprehensive technical specifications.
Common errors include inconsistent name formatting and incorrect date values. These mistakes cause indexing failures despite quality content. We provide detailed validation checks to prevent these technical oversights.
Optimizing Your Content for Better Indexing
Strategic content optimization for academic discovery requires a specialized approach distinct from conventional web search engine optimization. The algorithm prioritizes scholarly conventions and bibliographic accuracy over traditional metrics.
We guide publishers beyond basic compliance to maximize visibility. This involves intelligent keyword integration and robust technical formatting.
Integrating SEO Keywords and LSI Phrases
Effective optimization means using field-specific terminology naturally. Integrate methodology names and domain concepts into titles, abstracts, and body text.
Avoid oversimplified “plain language” titles. They often sacrifice the scholarly keyword density that matches actual researcher search behavior. This balance maintains integrity while boosting discoverability.
Every article benefits from this nuanced approach. It strengthens the connection between your content and relevant academic queries.
Ensuring Machine-Readable Formats and Mobile Responsiveness
Proper structure is non-negotiable. The title must be the largest text element. Author names should follow immediately below in a slightly smaller font.
Critical technical factors include:
- Dual-Format Availability: Provide both HTML and PDF versions for broader accessibility.
- Reference Linking: Link citations to their DOIs to strengthen your article’s network position.
- Mobile-Responsive Design: Ensure perfect rendering on all devices with fast loading speeds.
These steps ensure your publication meets modern technical standards. They significantly improve parsing accuracy and user experience.
google scholar journal indexing: Best Practices and Standards
Journals achieve lasting visibility through systematic application of proven architectural principles. We guide publishers beyond initial setup to maintain consistent quality standards that withstand platform evolution.
Complying with Inclusion Criteria
Successful indexing depends on two fundamental requirements. Your website must primarily host peer-reviewed scholarly articles with immediate abstract visibility. Avoid login barriers or complex navigation that blocks automated discovery.
The browse interface requirement is critical for crawler access. Every article URL must be reachable through simple HTML links from your homepage. Implement clear navigation structures rather than JavaScript-dependent menus.
We recommend architectural approaches based on collection size. Small publications benefit from single-page listings, while larger journal collections need browse-by-date interfaces. Very large publishers should create supplementary pages for recent additions.
Website availability remains non-negotiable for sustained indexing. Use proper HTTP status codes to communicate with crawlers—5xx for temporary issues, 4xx for permanent errors. Implement 301 redirects when moving content to preserve indexing status.
Metadata consistency across every publication prevents parsing failures. Maintain uniform author name formatting, publication dates, and language alignment. Established journals typically experience recrawling every 2-4 weeks when trust is maintained.
Our academic journal indexing services include comprehensive compliance evaluation frameworks. Systematically test URL accessibility, abstract visibility, and server uptime to ensure ongoing platform trust.
Navigating Legal and Compliance Considerations
Legal compliance represents a critical dimension of scholarly publishing that intersects directly with discovery platform requirements. We guide publishers through complex regulatory guidelines that affect content presentation and accessibility.
Medical publications must ensure HIPAA compliance when handling patient data. This involves proper de-identification protocols and consent management. These measures protect privacy while maintaining sufficient content availability for automated discovery systems.
Adhering to HIPAA, PhRMA Code, and Other Guidelines
Pharmaceutical research requires adherence to PhRMA Code standards. These guidelines prevent promotional content and ensure proper disclosure of industry relationships. Maintaining scholarly integrity supports long-term indexing success.
CME-accredited journal collections must follow ACCME Standards for Integrity. This includes conflict of interest mitigation and separation of educational content from commercial support. Proper documentation ensures compliance without affecting discovery platform requirements.
Copyright considerations allow flexibility in access models while meeting abstract accessibility needs. Sensitive research issues require consultation with institutional review boards before publication.
- HIPAA compliance ensures patient privacy in medical articles
- PhRMA Code maintains pharmaceutical research integrity
- ACCME Standards govern accredited educational documents
- Copyright flexibility balances access and protection
This guidance addresses common compliance issues but does not constitute legal advice. Consult qualified legal counsel for specific jurisdictional requirements governing your publication.
Leveraging Data-Driven Benchmarks for Success
Measuring performance through concrete benchmarks transforms abstract visibility goals into actionable strategies. We establish key performance indicators that quantify discovery platform effectiveness.
These metrics provide objective evidence of technical implementation quality. Publishers can demonstrate clear return on investment to stakeholders.
Analyzing Cost per Attendee, Speaker Honorariums, and Conversion Rates
Traditional event metrics translate effectively to publishing contexts. Cost per article published includes technical infrastructure and staff time investments.
Author processing charges parallel speaker honorariums in open access models. Citation conversion rates measure the percentage of views resulting in academic citations.
Established publications typically achieve discovery within 6-12 weeks. Newer sources may require 6-9 months to build algorithmic trust.
Indexed content receives up to 300% faster citation growth. This creates a virtuous cycle of increasing research impact.
We recommend tracking these benchmarks systematically. Search for recent article titles to monitor indexing success rates.
Analyze citation velocity differences between quickly indexed and delayed content. These comparisons reveal the tangible value of proper technical optimization.
Actionable Templates, Checklists, and Decision Frameworks
Practical tools and systematic approaches provide publishers with immediate implementation pathways. We bridge theoretical knowledge with hands-on application through comprehensive resource packages.
Downloadable Resources and Visual Infographics
Our pre-publication checklist ensures each article meets technical requirements before release. Teams verify HTML meta tags, PDF specifications, and website accessibility systematically.
The metadata validation template helps technical staff confirm proper implementation across all publication content. Consistent formatting prevents common parsing errors.
Using Gantt Charts and Budget Comparison Tables
Visual timelines map the complete discovery process with clear milestone markers. Publishers track progress from initial publication through full integration phases.
Budget comparison tables evaluate different hosting approaches objectively. They compare costs, staff requirements, and expected success rates across platforms.
Download our complete optimization toolkit including all templates and frameworks mentioned. Subscribe for updates on evolving requirements. Share this guide with colleagues and comment below with your implementation experiences.
Conclusion
Final implementation of the methodologies outlined represents the critical bridge between theoretical knowledge and tangible research impact. We’ve demonstrated that successful discovery hinges on precise technical execution combined with strategic optimization.
The compounding benefits of proper academic search integration far exceed the initial investment. Exponential visibility growth and accelerated citation accumulation create lasting value for your publication.
While algorithmic systems present challenges, our evidence-based strategies dramatically improve success rates. These approaches stem from extensive experience guiding publications to optimal indexing status.
Implement our comprehensive framework to transform your research visibility. Download our actionable templates to streamline your process. Subscribe for updates on evolving requirements. Contact our expert team for personalized guidance navigating technical complexities.
As scholarly communication evolves, robust discovery integration remains essential for maximizing real-world research impact.
FAQ
What are the primary benefits of having our academic publication indexed in Google Scholar?
Indexing significantly boosts your journal’s global visibility and accessibility. It increases the likelihood of your research being discovered, cited, and discussed within the academic community, thereby enhancing the publication’s impact and reputation.
What are the most critical technical requirements for successful indexing?
The most critical requirements include proper implementation of HTML meta tags, ensuring PDF files contain searchable text (not just images), and a correctly configured robots.txt file that allows our crawlers to access your scholarly content without restrictions.
How long does the indexing process typically take after we submit our publication?
The process can vary, but it generally takes several weeks. The timeline depends on factors like the volume of content, the accuracy of your metadata, and how easily our systems can crawl your website. Ensuring all technical guidelines are met from the start helps expedite this process.
Can content from institutional repositories be indexed, or is it only for publisher websites?
A> Yes, we actively index scholarly articles from institutional repositories, academic websites, and publisher platforms. The key requirement is that the content is scholarly in nature, publicly accessible, and meets our technical formatting standards for crawling and parsing.
What is the most common reason for an article or journal to be rejected from the index?
The most frequent issue is non-compliance with basic technical standards. This often includes PDF files that are image-based scans without searchable text, missing or incorrect meta tags, or website structures that block our crawlers. Adhering to our inclusion guidelines prevents these common rejections.